
Microsoft & Nvidia Built A Giant AI With Sharpest Human Communication Skills Yet
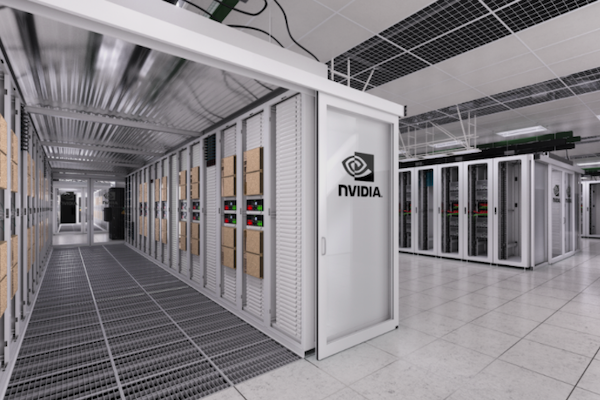
Nvidia’s Selene, MT-NLG’s “teacher.” Image via Nvidia
Almost every day, the tech field reaches a new breakthrough that surpasses the “surely this can’t be beaten” invention of the day prior. How does one even top a time crystal?
Well, here is one such example: Microsoft and Nvidia’s new sophisticated artificial intelligence that’s capable of replicating human language to what they claim is the highest degree of accuracy to date.
Named the Megatron-Turing Natural Language Generation model (MT-NLG), this boasts 530 billion parameters: three times more than the largest model of its type, OpenAI’s GPT-3 neural network.
It’s spread out across 105 layers, and the tech is said to “set the new standard for large-scale language models.” This power will allow it to accomplish a “broad” range of “natural language tasks,” which include things like common-sense reasoning, reading comprehension, and natural language inferences, to name a few.
Its mentors were Microsoft’s Turing-NLG model and Nvidia’s Megatron-LM, hence the name ‘Megatron-Turing’. Also part of its training was Selene, Nvidia’s machine learning supercomputer.
The model’s syllabus consisted of DeepSpeed, an open-source deep learning library, and a giant dataset called The Pile. This is made up of multiple smaller datasets of text collected in an effort to create large language models.
It adds up to around 825GB worth of data, which includes text collected from places off the internet like Wikipedia, academic journals, and news sites. A total of 1.5TB of data was used to train the model, but this only took just a little more than a month.
This, unfortunately, also means that the machine might have picked up on some “stereotypes and biases.” It’s kind of like cursing in the presence of a toddler and having the child later walk up to Grandma and proudly repeat that fancy new word.
“Microsoft and Nvidia are committed to working on addressing this problem,” the blog post explains. “We encourage continued research to help in quantifying the bias of the model.”
The disclaimer continues, “In addition, any use of MT-NLG in production scenarios must ensure that proper measures are put in place to mitigate and minimize potential harm to users.”
After all, no one’s perfect. Not even MT-NLG.
[via New Scientist, image via via Nvidia]
Also check out these recent news


